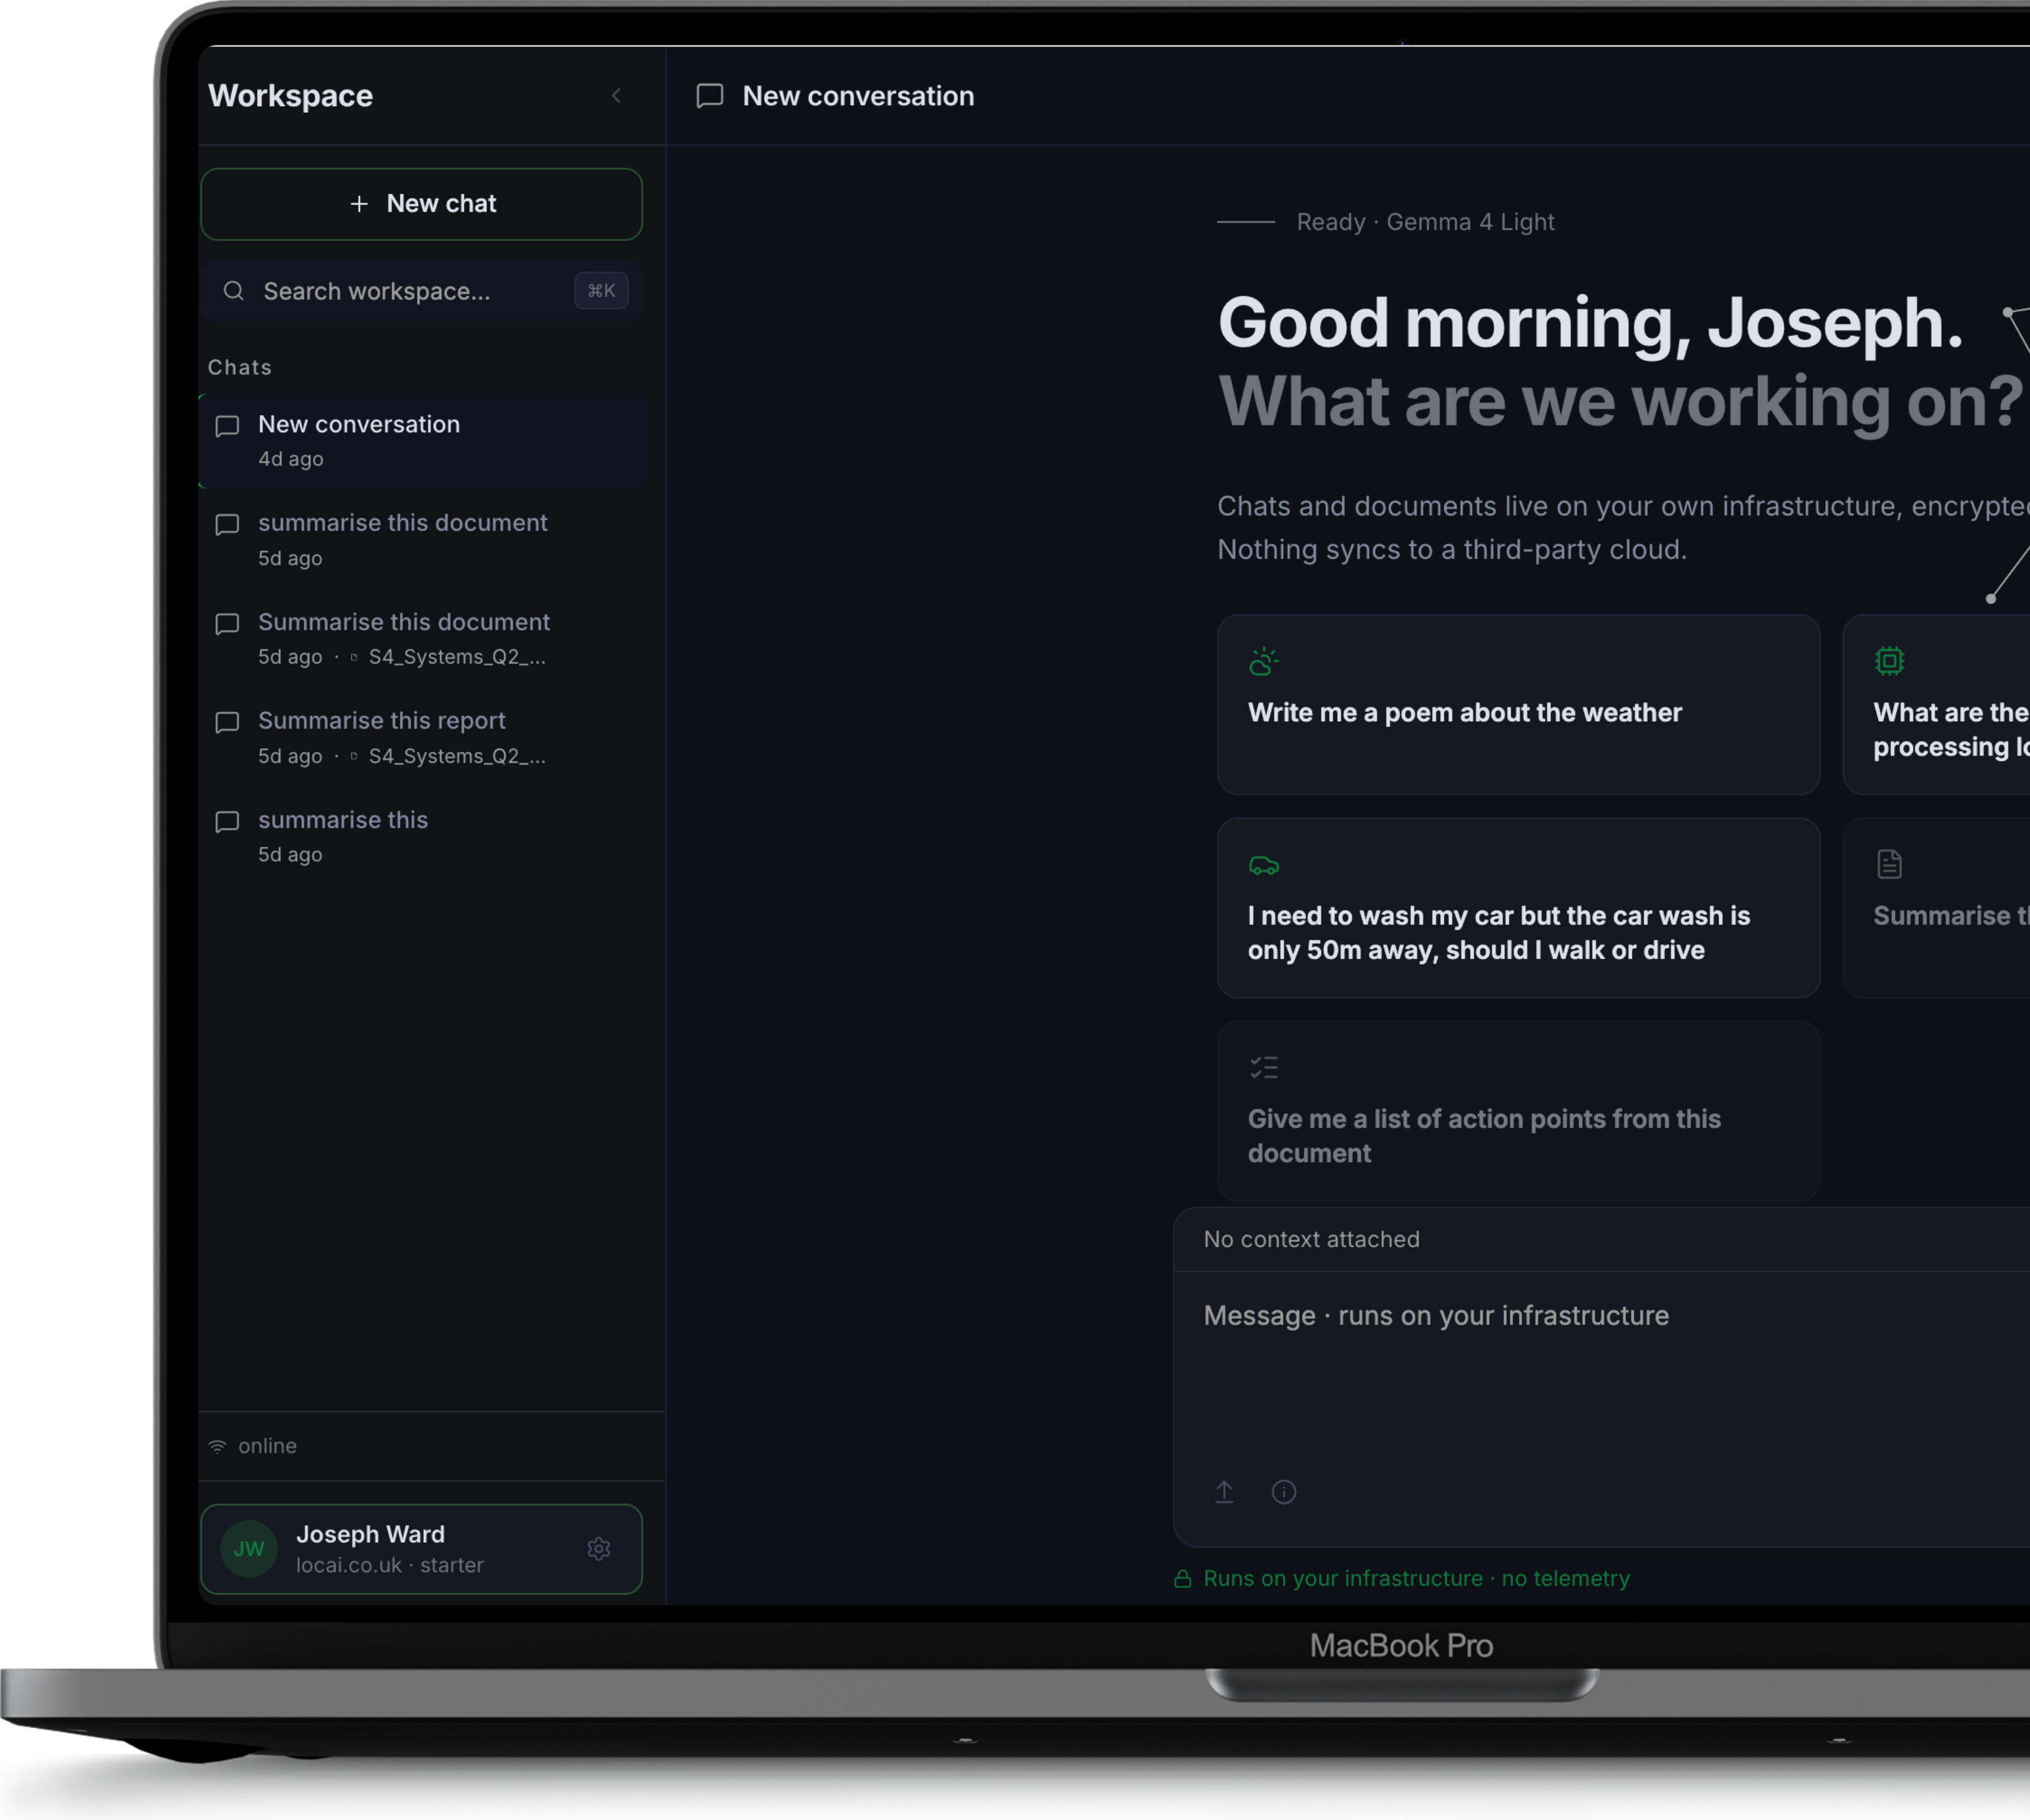
Give employees one place to work with AI, while your organisation controls the models, data boundaries and spend. Aventail™ Enterprise connects Workspace to your own hardware and approved frontier APIs, with Aventail™ Link applying your policies to each request.
Give teams a private AI workspace for conversations, documents, data and workflows. Run supported models on your own infrastructure and choose when approved cloud APIs may be used.
Aventail™ Link combines an LLM gateway and inference engine, connecting your applications to supported models on your hardware and approved external APIs. Routing policies are applied locally on each machine.
Keep sensitive work on approved infrastructure, use existing capacity for suitable requests and allow frontier APIs when the work needs them.
Team requestSensitive team request
On this machineAventail™ Link local policy
Execution destinationOn-premises machine
Illustrative policy example
Sensitive work
A permitted model runs on an on-premises machine equipped with Aventail™ Link. The policy keeps this request within approved infrastructure.
Contract review on an internal server
Illustrative workflow: a team asks a supported model to summarise a confidential contract on an approved internal server running Aventail™ Link. The device policy selects that server as its network-peer primary, with the exact model available and Serve other devices enabled. No external provider or fallback is configured; if the server is unavailable, the request fails. Aventail™ Control distributes the policy and stays outside the inference request path. Review document storage and access separately from inference routing.
Set which models and destinations each workflow may use. Apply the same data boundaries to fallback paths.
Control when you pay for external AI
Use your devices and servers for suitable work, and set when paid APIs are allowed. Local execution still has hardware, energy and platform costs.
Manage machines and policy together
Use Aventail™ Control to distribute models, policies and keys, then review device and routing activity across machines running Aventail™ Link.
Roll out your AI tools. Keep one set of rules.
Aventail™ Connect is available for enterprise deployment through our fleet management tooling. Roll it out across employees’ machines so supported model requests from Claude Desktop, Claude Code and OpenCode follow your organisation’s routing policies. Manage policies centrally through Aventail™ Control, with the LLM gateway in Aventail™ Link applying them on each machine.
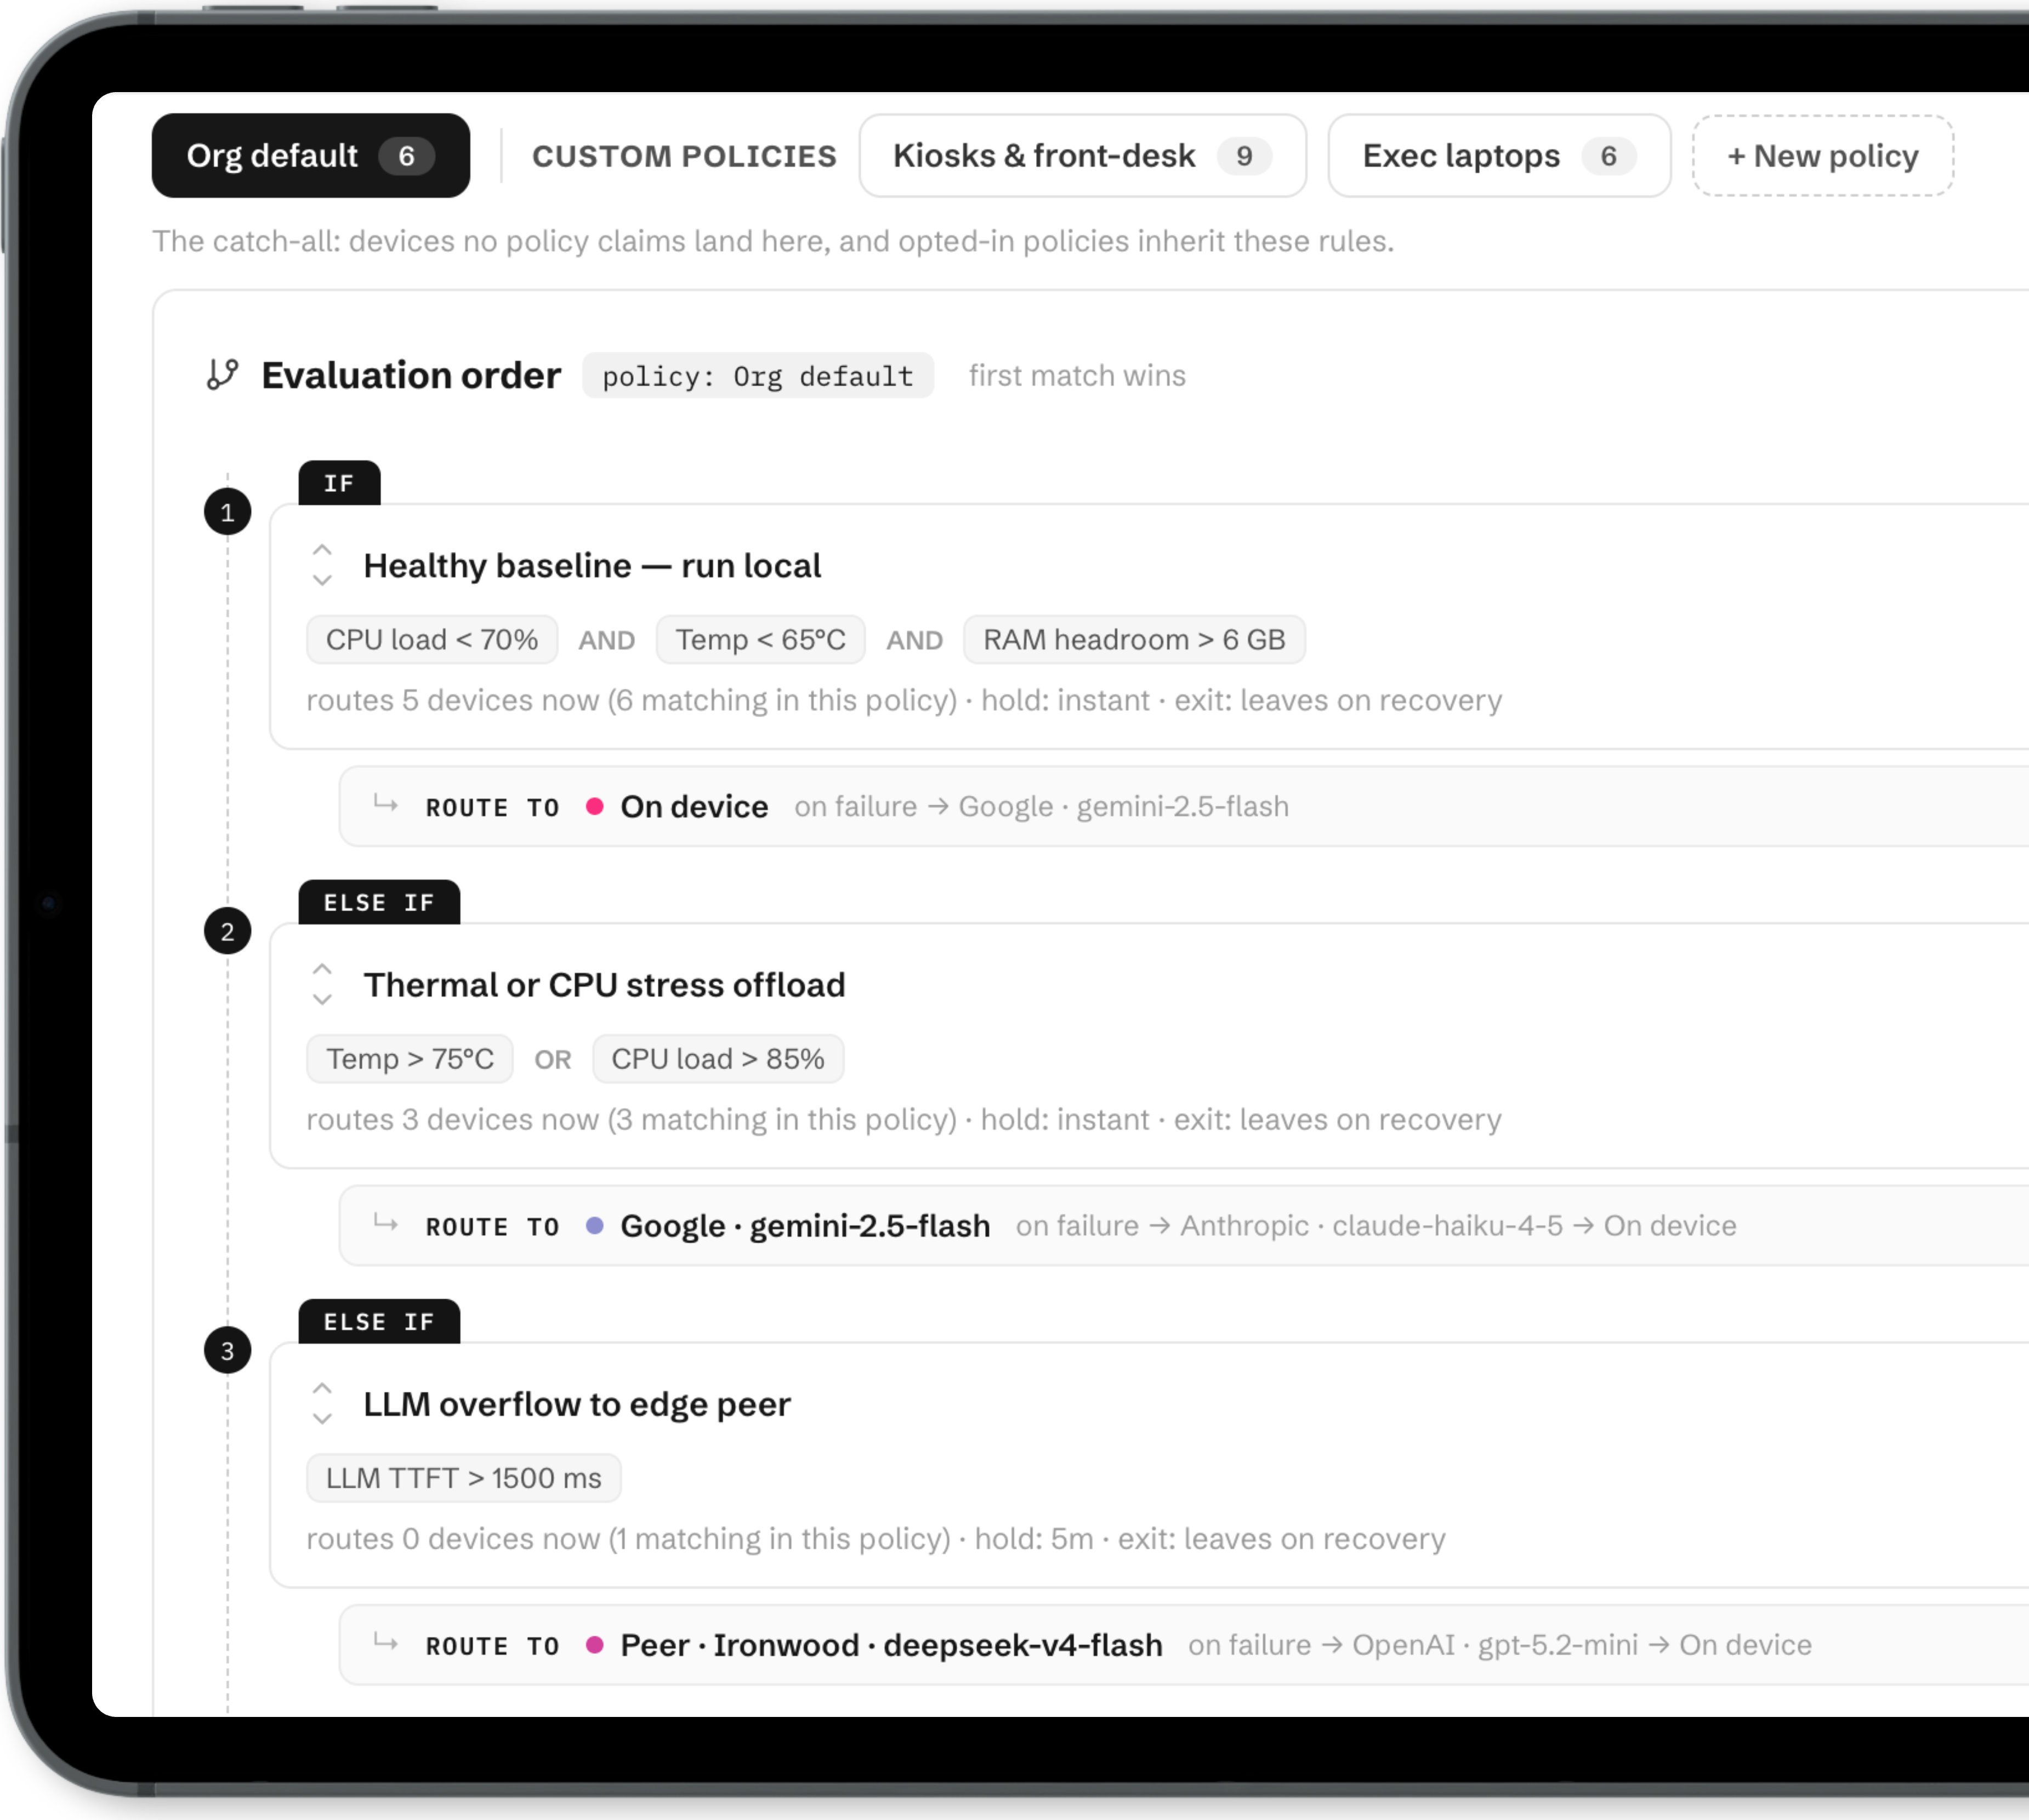
Aventail™ Control — routing rules and fallback order
See the rules. Keep prompts out of hosted Aventail™ Control.
Aventail™ Control lets you manage routing rules and fallback order, with configuration distributed ahead of requests.
The hosted Aventail™ Control service receives device and routing events, not prompts or responses. An approved external provider processes the request through your organisation’s own account. Aventail™ Control can also be hosted on your infrastructure.
Local execution keeps inference on the machine. A policy-permitted remote destination receives the request sent to it. Hosted Aventail™ Control receives management, device and routing events, not prompt or response bodies. Local execution alone does not determine application storage, analytics or plugin behaviour; review those settings. Read the architecture and usage analytics guidance.
Where can our AI requests run?
On an eligible local device, another approved reachable peer running Aventail™ Link, or on-premises, private-cloud or provider machines running Aventail™ Link. Approved frontier APIs run at their providers, using your own provider accounts. Model support, connectivity, access and your policy determine which destinations are eligible.
Can routing use model and device performance?
Yes. Integration with the inference engine lets Aventail™ Link combine model suitability and performance with device capacity and conditions, query content and organisation policy in a local decision. Constraints restrict eligible destinations before preferences select among them.
Which models and hardware are supported?
Support depends on the runtime version, operating system and architecture, model engine and format, and available resources. Current documentation lists Mac Apple Silicon, Linux x64 and Windows x64 packages; package availability does not mean every model or machine is supported. Read the compatibility guide.
Where are routing policies applied?
Aventail™ Control configures and distributes policies. Aventail™ Link evaluates requests locally and applies restrictions to destinations and fallback paths. Aventail™ Control stays outside the inference request path. Read how Aventail™ works.
Can we use our own models alongside frontier APIs?
Yes. Run supported open-weight models on your own compute and permit external calls through your own provider accounts. The same policy layer governs those choices without requiring an all-cloud or all-local deployment.
Aventail™ Link is not currently open source. We intend to open-source it by the end of 2026 and are evaluating the appropriate licence and release approach. Link 1.0 was open source, and we want to bring the current generation to the community too. We will share the scope, licence and contribution process when they are confirmed. Read our open-source plans.
Start with one useful workflow.
Bring one employee workflow, your data requirements and the hardware or model services you already use. We’ll map a practical starting point.